November 22, 2024
Before you build AI: feasibility, data, ethics and regulation
In this article:
Is this really a problem for AI?Data: access comes before qualityExisting models firstCosts to understand before you startEthics, GDPR and the new AI ActWhat comes out of a feasibility studyMost conversations about AI we have had this year start in the same place: a company has seen what modern models can do and wants to know whether they can do the same for its business. A quick demo shows that something works on ten hand-picked examples. It does not show whether it will work on your data, at your scale, within your budget and within the law.
That is why we treat a feasibility study as the first step of any AI project. We wrote about feasibility studies back in 2021, and the principle has not changed. What has changed is the list of things to check. This year we supported a publicly co-funded AI feasibility study on road traffic analysis. It covered the choice of algorithm, data protection and ethics, and whether people without programming skills could use the result, and it was followed by a proof of concept. Below is what such a study looks like for us, and what this one taught us.
Is this really a problem for AI?
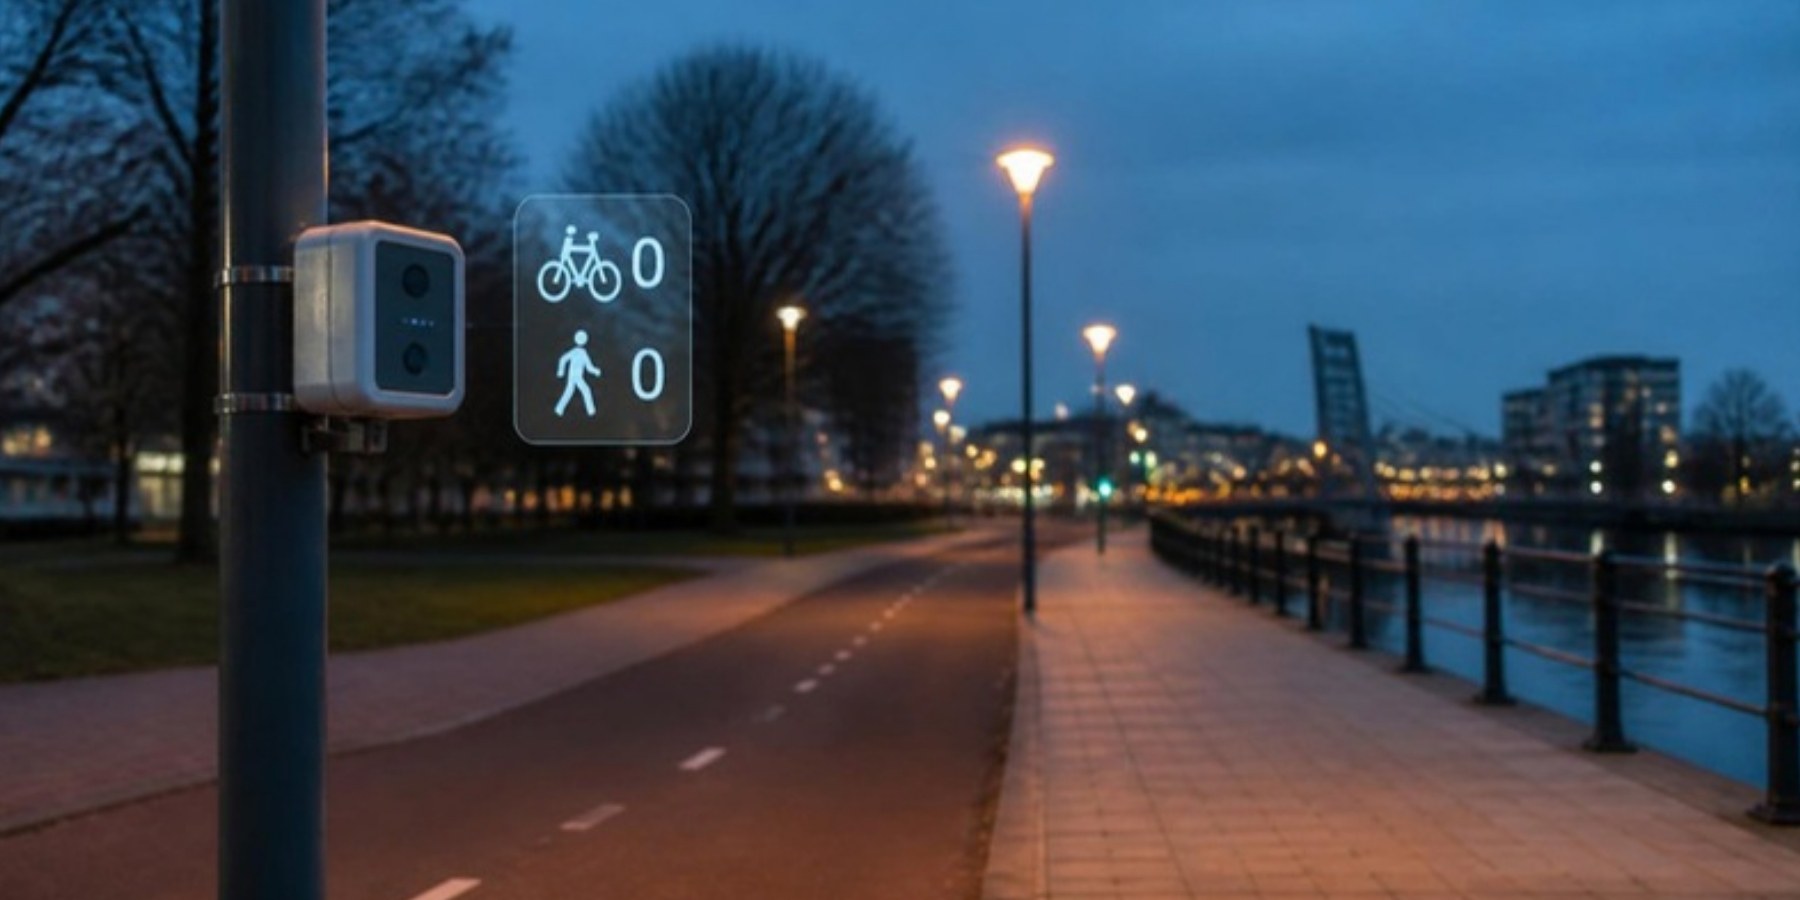
The first question is whether the problem needs a model at all. Many "AI" tasks are really about rules, integrations or better reporting. AI earns its place where the input is messy, such as video. Our case qualified. The idea was to turn existing traffic webcams into a source of mobility statistics, counting cars, buses, bicycles and pedestrians without installing new sensors. Even then we ask a few plain questions:
- What decision will the output support? Here: statistics for planners, not real-time control of anything.
- How good does it need to be? An error rate that is fine for statistics may be unacceptable for anything that triggers an action affecting a real person.
- Who will run it? Some public organisations may only build and operate such systems with their own staff, or face strict procurement rules. That is a feasibility finding too, and easy to check early.
Data: access comes before quality
We expected the hard questions to be about image quality: night, rain, low resolution. The first obstacle was access. Many cities do not allow direct access to their camera streams, for reasons ranging from data transfer costs to concerns about how the footage might be reused. In Austria and Germany most public traffic webcams are embedded in web pages rather than offered as a stream. A tool that "works on any camera" therefore has to cope with that, or the project has to agree data access first.
The second question was training data for classes that public datasets cover poorly, such as cargo bikes, scooters or the number of people in a car. Synthetic images, generated and labelled automatically with open-source tools, are one answer: they are cheaper than manual labelling, add variety and contain no real people. They also have real limits: generated images lack the nuance of real scenes, some come out with obvious errors, and a model trained only on them may not generalise. A human check of generated data before training is a sensible safeguard.
Existing models first
We started from a ready-made detector pre-trained on the public COCO dataset, which already covers people, bicycles, cars, buses and trucks; anything beyond those classes means training, which is where synthetic data comes in. This matched what we had seen earlier this year with object detection on camera devices at the edge: pre-trained detectors plus simple filtering get you surprisingly far, and training is justified only where the numbers show a gap. Two points are easy to miss:
- Licences. Some popular detectors come with copyleft licences that impose obligations on commercial products. Check before you build on them.
- Where the model runs. A first demo that is too slow on an ordinary laptop is common. The choice between a cloud GPU and an edge device at the customer's site affects cost, latency and privacy, since an edge device keeps images local. For a proof of concept, a cloud instance that can be started and stopped on demand is often the quickest way to show results.
Costs to understand before you start
Figures depend on the case, but the categories are always the same: data collection and labelling, compute for experiments and training, inference multiplied by cameras, hours and years, integration, and maintenance. GPU time quietly grows, so automatic shutdown of idle instances is worth building in from day one. Maintenance is most often forgotten: an AI system needs looking after for as long as it runs.
Ethics, GDPR and the new AI Act
Anything that processes images of public spaces processes personal data. Under GDPR that means a clear legal basis, data minimisation and defined retention periods, and systematic monitoring of public areas will usually also require a data protection impact assessment. The most effective measure is technical: keep only the counts the analysis needs and discard the frames, ideally on the device itself.
Since 1 August 2024 the EU AI Act has been in force, applying in stages. It sorts AI systems by risk: prohibited practices, high risk (strict requirements for data, documentation, human oversight and accuracy), limited risk (transparency obligations) and minimal risk. The prohibitions apply from February 2025 and include, among others, untargeted scraping of facial images to build recognition databases and, with narrow exceptions for law enforcement, real-time remote biometric identification in publicly accessible spaces. Counting vehicles and pedestrians is far from that, but a feasibility study should classify the planned system before development starts, because the classification shapes the design.
What comes out of a feasibility study
The result is a decision, not just a report: go, go with changes, or stop. It rests on test results on real data, a data plan, costs and risks, the legal classification and a scope for the next step. Stopping is a valid outcome, and far cheaper now than after months of development.
AI can do remarkable things, but only when the problem, the data and the legal framework fit together. Checking that fit is how we start AI projects. If you are considering one and want to check it before you build, get in touch with us.
Quote a project! Get advice.
Let’s talk about your project
Drop us a line or book a short intro call — we’ll get back to you with the right people on our side.
E-mail usinfo@embiq.comBook an intro call (opens in a new tab)
Let’s investigate your project concept and its current status together.

Expect an initial project scope proposal, time and cost estimation from us.

The consultancy will be protected by the NDA.